Media
17 signed skills and professions from 1 vendor, with 1 video and 11 articles. Read any page free; a free account downloads them.
 Skill4 images
Media Generator
@di-atomic · Media
The eyes and hands of the studio — guidance for generating brand-keyed images, videos, voiceovers, carousels, screenshots, and composed media. The agent composes the generation itself following SKILL.md: every model call SpiderGate-routed per-tenant (Mode A gate proxy / Mode B credential-pool), every asset SpiderMedia-persisted, every output verified by the bundled enforcement scripts. 8 use-case recipes + 33 evidence-bundled registry items + a client-grade verify-all gate. v1.3.0: converted to the guidance-only meta-package shape (skills:[] + peer_dependencies) — no phantom backend; agents reach it via skill_read.
 Skill4 images
Hook Generator
@di-atomic · Media
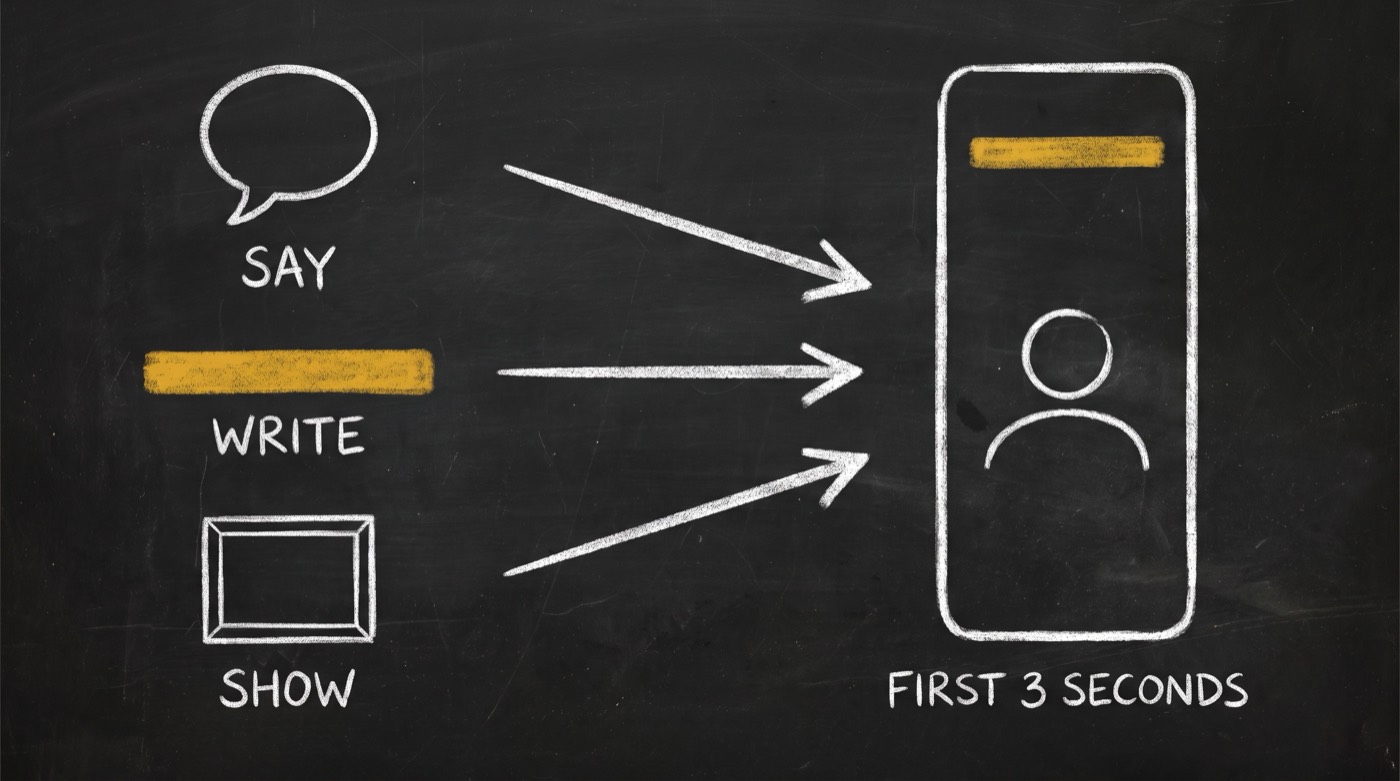
Generate platform-tuned, voice-aware hooks for any surface — LinkedIn, X/Threads, Instagram captions, cold-email subject lines, regulated-product copy — and the first 3 seconds of a TikTok, Reel or Short, written as what is said, what is on screen and what the first frame shows. Guidance-only: the agent's own LLM composes hooks following SKILL.md, installs from 64 source-attributed exemplars in registry/ (11 of them short videos measured against their creator's own median), and gates output with six enforcement scripts (length / AI-slop + BPR/CLP compliance / structure diversity / build-diary launch headlines / video hook / coordination) — PASS/FAIL with numbers. Recipes route on occasion first, then platform. The opener primitive that feeds post-writer, section-designer, outbound-engine and copy-engine's video script. Multilingual DE/FR/ES/RU/RO gated pending native-speaker validation.
 Skill4 images
Section Designer
@di-atomic · Media
Design a webpage section, page hero, pricing block, feature grid, cta, faq, footer, testimonial in any of 150 named design-system languages (linear-app, stripe, vercel, apple, airbnb …) or 5 mood directions (Editorial / Brutalist / Glass / Soft-Neo / Terminal). Runs a mandatory script-driven critique (WCAG AA contrast, tap-target size, AI-slop blacklist, token-verbatim, heading hierarchy) before hand-off. Hands off composed markup + tokens + script receipt; the agent uses its own publishing skills (@spideriq/spiderpublish for CMS, @opvs-ai/agentdocs for archive) to ship. Adapted from nexu-io/open-design (Apache-2.0) — see ATTRIBUTION.md + LICENSE-upstream.
 Skill4 images
Explainer Illustrations
@di-atomic · Media
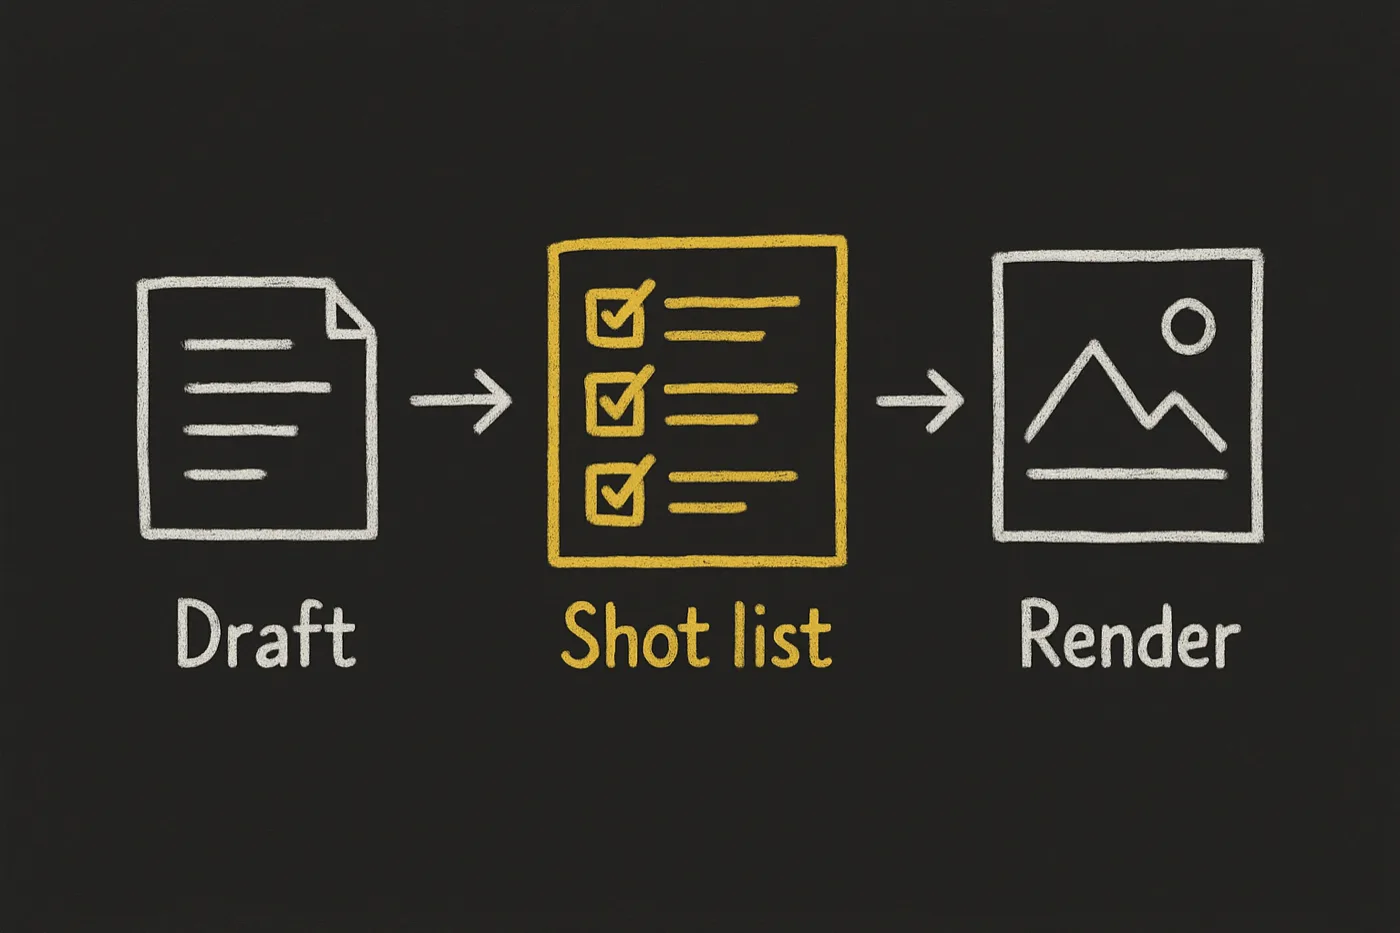
The planning brain between copy and render. Reads an article / case study / changelog / concept brief, extracts the cognitive anchors, and emits a structured shot list of 4–8 illustrations that EXPLAIN the topic (not decorate it) — one insight per image, the right composition pattern, one of 5 style packs (clean-line-art / whiteboard-sketch / isometric-tech / corporate-flat / editorial-illustration), with a render-mode hint and a compliance gate for regulated topics. Hands the prompts to @di-atomic/media-generator to render (SpiderGate-routed, reference-anchored, SpiderMedia-hosted). 6 use-case recipes + 39 evidence-bundled registry items + 5 PASS/FAIL enforcement scripts (incl. brand-fidelity). guidance-only skill (nested skills:[{id,schema}] with a no-methods schema + peer_dependencies) — agents reach it via skill_read.
 Skill4 images
Post Writer
@di-atomic · Media
Draft platform-tuned full social posts AND long-form Articles — LinkedIn posts + Articles, X posts + threads + Articles, Instagram caption + carousel, Threads, Facebook, YouTube (title + description) and Reddit (advise-only). Voice-aware (reads voice.md), hook-aware (composes hook-generator output). Each post scored against 2026 platform algorithm patterns, structure rules, an AI-slop blacklist, and 74 metric-bearing real exemplars + 5 enforcement scripts. GUIDANCE-ONLY: no backend and no methods — the agent's own LLM composes posts following SKILL.md, read via skill_read from the nested skills/post-writer/ layout; state persists via the upstream OPVS Coordination skills (agentdocs / agentmemory / agentboard) declared as peers. Knows the SpiderIQ publishing stack: social → vibe-publish; owned site → spiderpublish; assets → spidermedia.
 Skill5 images
Iconography
@di-atomic · Media
Choose and specify icons — which set, which token, what size, what colour, RTL placement — and say whether the licence permits it in a paid client deliverable. Ships no icon files: the catalogue is commodity (Iconify maintains 334,616 across 236 sets), so what ships is the contract layer the 19 consuming skills describe and nobody had written down. 43 semantic slots harvested from those skills and resolve-verified live, 236 sets licence-classed against SPDX, and four scripts that print numbers. GUIDANCE-ONLY: the agent's own LLM composes the work from the bundled references, recipes, registry and learnings.
 Skill4 images
Podcast
@di-atomic · Media
The writer + director of a podcast episode. Reads a source corpus (URLs / docs / notes / research output) and produces a multi-speaker episode script (1-4 speakers, full script control) + search-optimized show-notes, then hands TTS to media-generator and publishing to distribution-launcher. Compliance-aware (REACH/CLP/biocide claim gate), multilingual (EN floor; DE/RU/FR/RO planned), brand-voiced hosts. 7 use-case recipes + 34 evidence-bundled registry items + 4 PASS/FAIL enforcement scripts. Guidance-only meta-package.
 Skill5 images
Infographic
@di-atomic · Media
Build a real information graphic from data or a document — full-scale, text-dense, client-grade. Routes between an HTML render path and a raster path, and checks the result with five scripts that print numbers instead of adjectives. Every cap is measured: 25 published infographics and 8 controlled render tests. Those tests found that the field's stated reason for avoiding image models is out of date — text stays correctly spelled to 20 labels; what breaks at 8 is which labels appear at all. So the raster path is capped at 6 and verified by an exact set comparison on the rendered image, not by a legibility judgement. GUIDANCE-ONLY: the agent's own LLM composes the work from the bundled references, recipes, registry and learnings.
 Skill5 images
Persona Builder
@di-atomic · Media
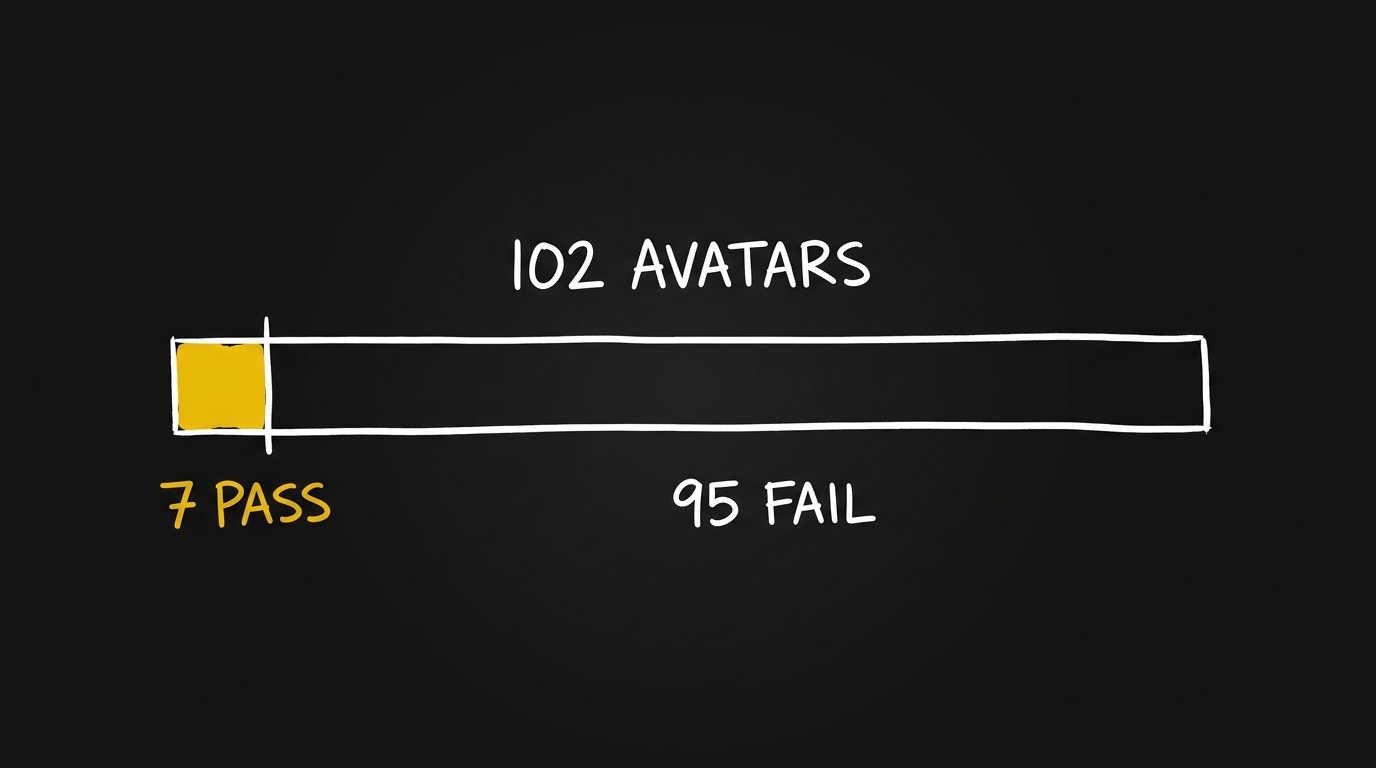
Author an AI employee somebody would actually hire. Researches the real profession on LinkedIn via SpiderPeople — title vocabulary, skill frequency, self-description register, name and sex distribution, and the visual register practitioners present in — then composes the persona from those distributions rather than from imagination. Two modes: `product` (identity, goal, falsifiable rules with explicit refusals) and `character` (the full visual identity: 3-paragraph seed prompt, face-consistency prompt, 6 variation prompts, voice), rendered through @di-atomic/media-generator. Carries a house visual standard that 7 of 102 shipped personas currently meet — three camera registers, a 13-row anti-pattern table, and the rule that a reference image fixes identity so the prompt must stop describing it. 5 PASS/FAIL scripts enforce it, including a likeness gate that fails closed. Guidance-only — agents reach it via skill_read.
 Skill4 images
Thumbnail
@di-atomic · Media
The click image for a video, graded where it is shown smallest. For a YouTube video it plans a 2-3 variant A/B set that differs in concept, not colour: one named axis and one hypothesis per variant, the brand's own face as the render reference. For a Short, Reel or TikTok it makes one cover. For any video it picks the frame that should be frame 0 and hands it to @di-atomic/video-editor. Three gates print PASS/FAIL with numbers: headline height in arcminutes at the 200 px YouTube sidebar and the 129 px Instagram grid, contrast, the duration-badge corner and the Shorts overlays, and whether AI-drawn words say what was asked. A host without OCR gets UNVERIFIED, never PASS. 5 recipes, 37 registry items, 5 reference procedures. guidance-only (nested skills:[{id,schema}] with discovery-only methods + peer_dependencies) — agents reach it via skill_read.
Chalkboard Explainer
@di-atomic · Media
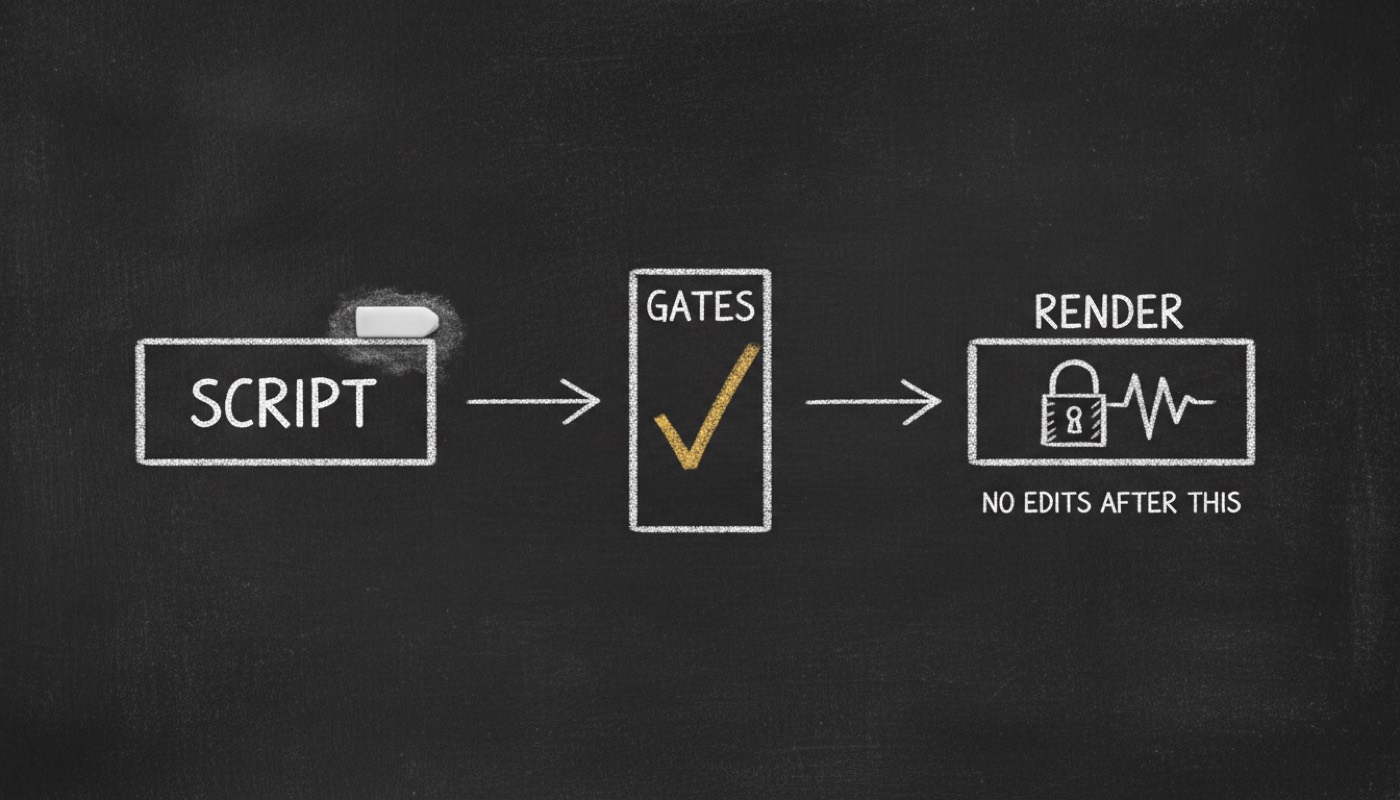
Guide a narrated chalkboard explainer from an approved six-part script brief through transparent illustration layers, meaning-first camera moves, licensed audio and a reviewable delivery pack. Five recipes and five local checks validate layer assets, scene timing and project inputs. Guidance-only; delegates generation, rendering and final video/audio verification to specialist peers.
 Profession4 images
Article Writer
@di-atomic · Media
Writes one long-form article (blog, Substack, LinkedIn or X Article) from its board card, in the brand's voice, with a sources file behind every number, then hands it to the checkers. Works from a board. 8 links, 4 workflows. First publish, probationary.
 Profession4 images
Video Producer
@di-atomic · Media
Takes a finished script from its board card to one verified video: shot list, generated and recorded assets, edit, thumbnail, and every gate's PASS/FAIL on the card. Works from a board. 12 links, 4 workflows. First publish, probationary.
 Skill▶ 15 images
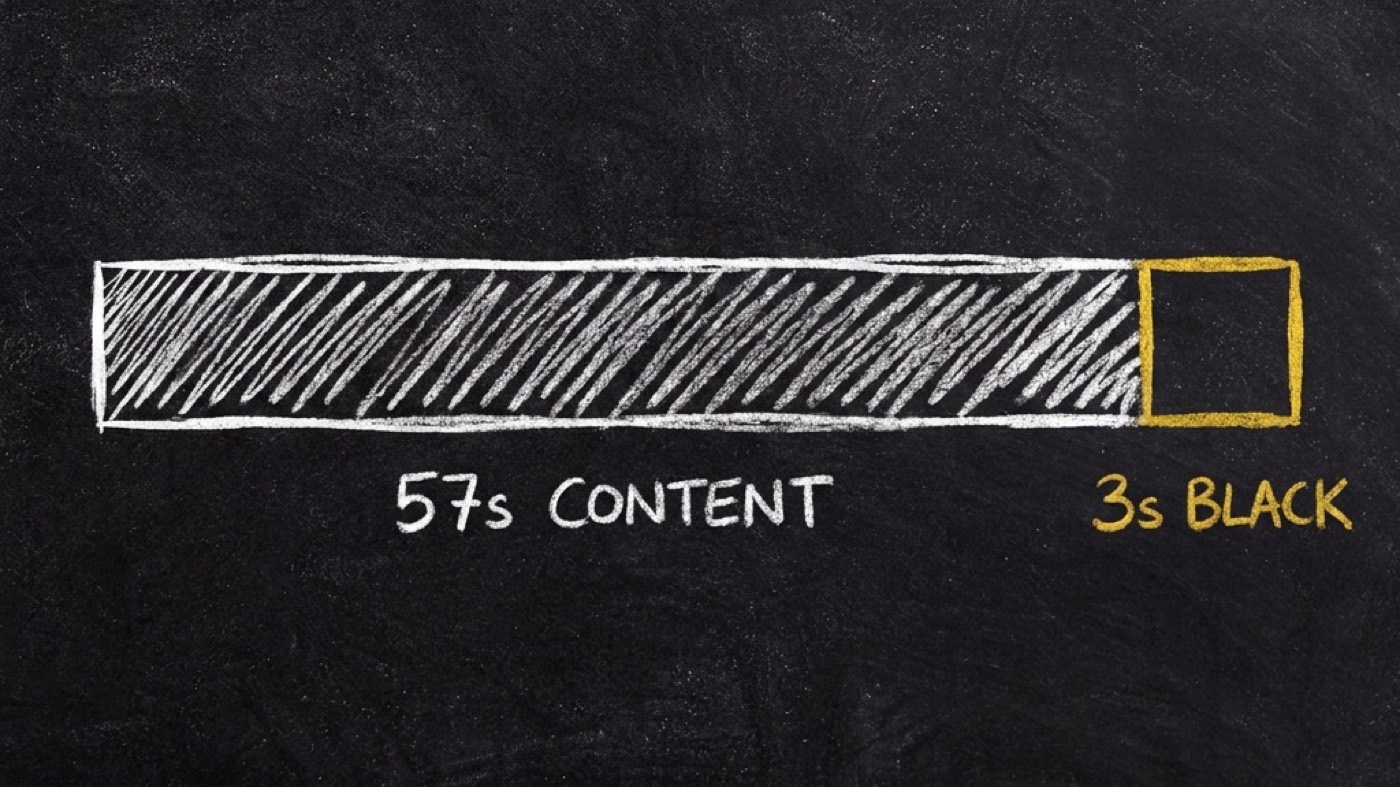
Video Director
@di-atomic · Media
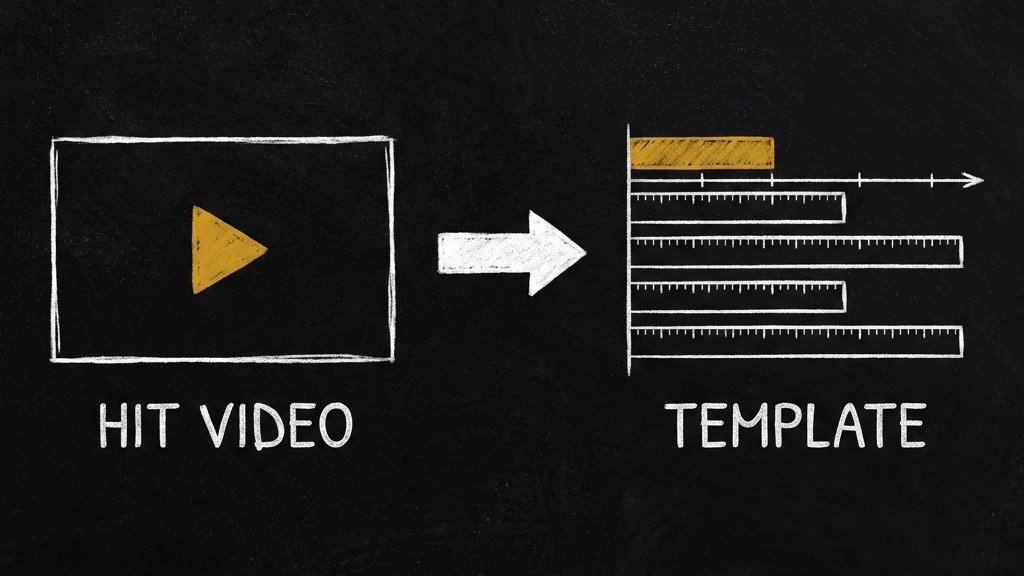
Script in, shot list out — the one artifact the camera, the screen recorder and the editor all read. Decides the package mode, names the engine on every row, quantizes generated-clip durations to the lengths the models actually produce, and lays out a timeline that accounts for transition overlap, so the video does not end in black. Cuts follow a seam rule in the renderer's own transition vocabulary. Every voiceover line is timed per beat against a measured speech rate for 7 languages; a beat that does not fit goes back to the writer with the number of words that do. Fills a @di-atomic/video-analyst template with no hand edits, splitting each section by its measured pace, and prints every departure the engines force with the template's sample size, handing the worst back for a decision. Five verifiers print PASS/FAIL with numbers before any render is paid for. 5 recipes + 14 registry items + 7 references. guidance-only — agents reach it via skill_read.
 Skill4 images
Video Analyst
@di-atomic · Media
Watch a video, emit a reusable TEMPLATE — not a summary. Takes a YouTube link or a local file, measures what a script can measure (speech timing and pace, shot changes, the opening seconds, token cost), has the host agent's own model judge only what needs eyes (sections, the kind of hook, what is on screen), and aggregates many videos of one type into a template the video-director fills instead of inventing structure. Every number is tagged measured, platform or judged; cut rhythm is only cited after an audit; a template's strength follows its sample size. Five gates print PASS/FAIL with numbers. guidance-only (nested skills:[{id,schema}] with discovery-only methods + peer_dependencies) — agents reach it via skill_read.
 Skill5 images
Video Editor
@di-atomic · Media
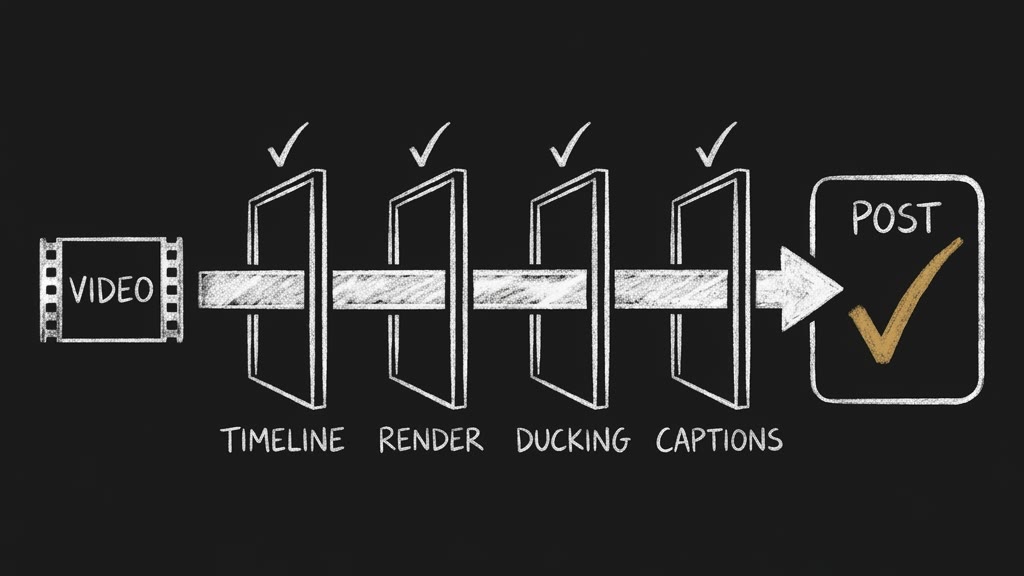
Shot list and finished assets in, one verified video out. Where the agent's shell has ffmpeg (Claude Code, Codex, Antigravity) it renders locally from a computed filter graph: transitions that account for overlap, a voiceover placed on the timeline, music ducked under the voice with an envelope that does not pump, captions burned inside the platform safe zone, the poster baked in as frame 0, loudness set for the destination. Where there is no ffmpeg (an OPVS agent) it emits SpiderVideo's create_video payload and prints every field that path cannot honour. Four gates read the finished file, so they verify this render, a SpiderVideo render, or anyone's, and print PASS/FAIL with numbers. 4 recipes, 25 evidence-bundled registry items, 5 reference procedures. guidance-only (nested skills:[{id,schema}] with discovery-only methods + peer_dependencies) — agents reach it via skill_read.
 Profession4 images
Graphic Designer
@di-atomic · Media
Graphic Designer — a hireable craft role that produces a brand's visual deliverables end to end and hands back a rendered, hosted, provenance-carrying asset with its verifier report attached. The four design skills it reads each stop somewhere different: iconography emits a token and a licence verdict and ships no files; section-designer composes markup and explicitly stops at hand-off; explainer-illustrations plans a shot list and hands prompts onward; infographic writes HTML itself but cannot render raster. A buyer who installs all four owns four half-pipelines and the job of knowing which to open. This role routes the request and CLOSES the pipeline — it holds the one render call and the asset catalogue that none of the four hold. It renders, it proves what it rendered with the owning skill's own scripts, and it refuses to deliver a graphic containing a figure that is not in your source. It does not write the words and it does not put anything live. 12 links, 5 workflows.