CRO Optimizer
Close the CRO loop. After a fix ships, cro-optimizer reads the test outcome (PostHog/GA4), decides whether the result is REAL — running a mandatory significance gate + a causal-overreach gate PostHog doesn't — reverts confirmed losers via SpiderPublish, and writes the verified brand-prior back into cro-audit's baseline so the program learns instead of believing its own wins. GUIDANCE-ONLY: the agent's own LLM does the reasoning per SKILL.md, grounded in 18 test-outcome evidence cards + 6 references + 5 cycle recipes + 2 enforcement scripts; state persists via the upstream OPVS coordination skills declared as peers. It decides + routes — it does not measure (PostHog/GA4 do) or deploy (SpiderPublish does).
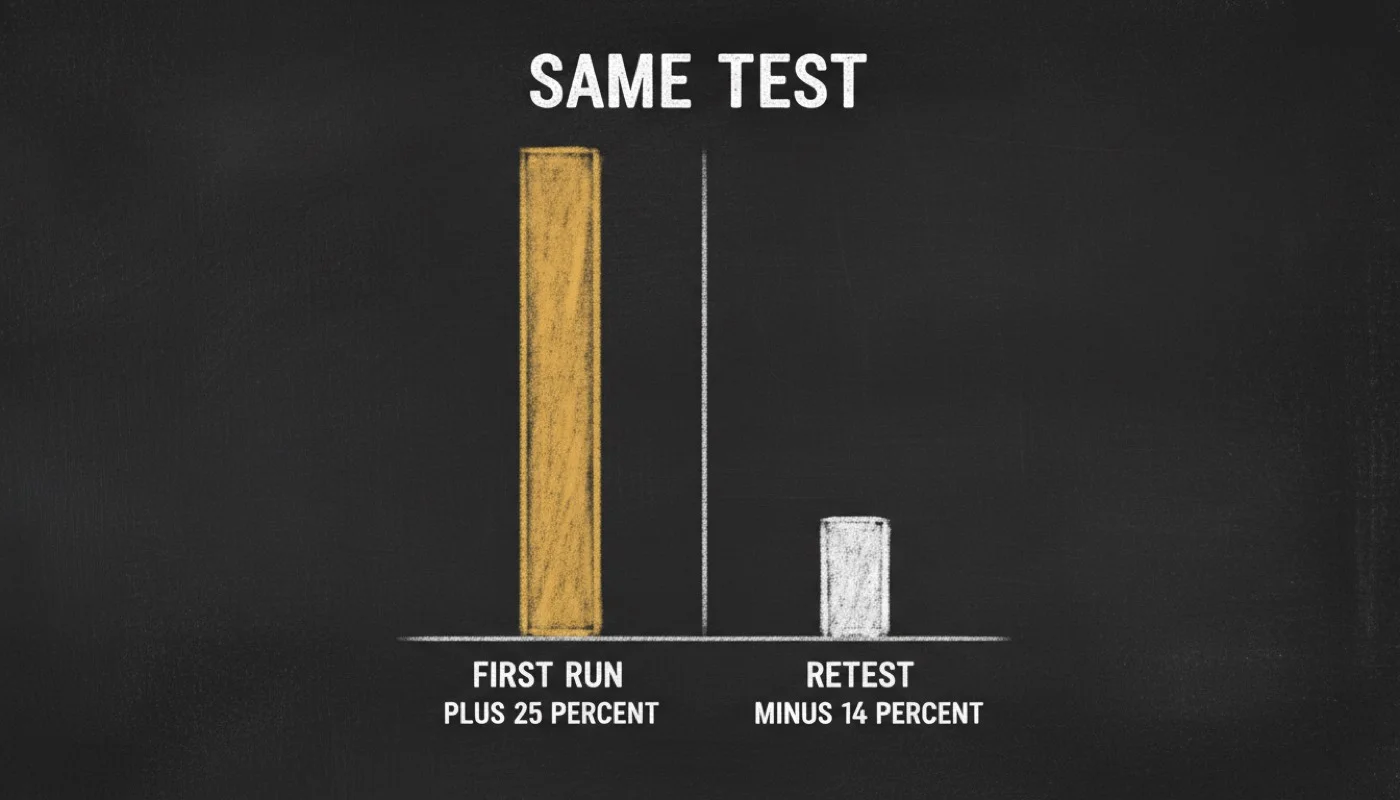
My best CRO win was +25%. The retest said minus 14%.
Nothing had broken. Both numbers were real. I had simply treated a single run as a fact, written it into the baseline, and let every decision after that stand on it. That is the failure this skill exists to stop.
cro-optimizer is the third skill in my CRO chain. cro-audit finds what is broken, cro-actions plans the fix, and this one reads the outcome after it ships and decides whether the result survives. Two gates run on every result: a significance gate (sig floor, duration, power against a declared MDE, peeking, thin samples) and a causal-overreach gate (discount applied, no certainty language, stable estimate, confounds checked, guardrail metric named). Both must pass, every time.
The numbers behind those rules: about half of all tests are statistically null, peeking pushes a 5% false-positive rate to 26%, and test wins overstate production by 20-50%. So the lift that reaches your baseline is discounted, and it is smaller than the one in the deck.
Worked example: a pricing test returns +18%. Provenance is read from the deploy log, both gates pass, the guardrail is flat, and the verdict is won at a projected +9-14% in production. Run the same call on day 3 and the answer is inconclusive, because 3 days is not 7 and the test was peeked.
Guidance-only. 18 evidence cards, 6 references, 5 recipes, 12 learnings, 2 scripts, zero methods. PostHog and GA4 measure, SpiderPublish deploys and rolls back, and this skill decides between them.
Features5
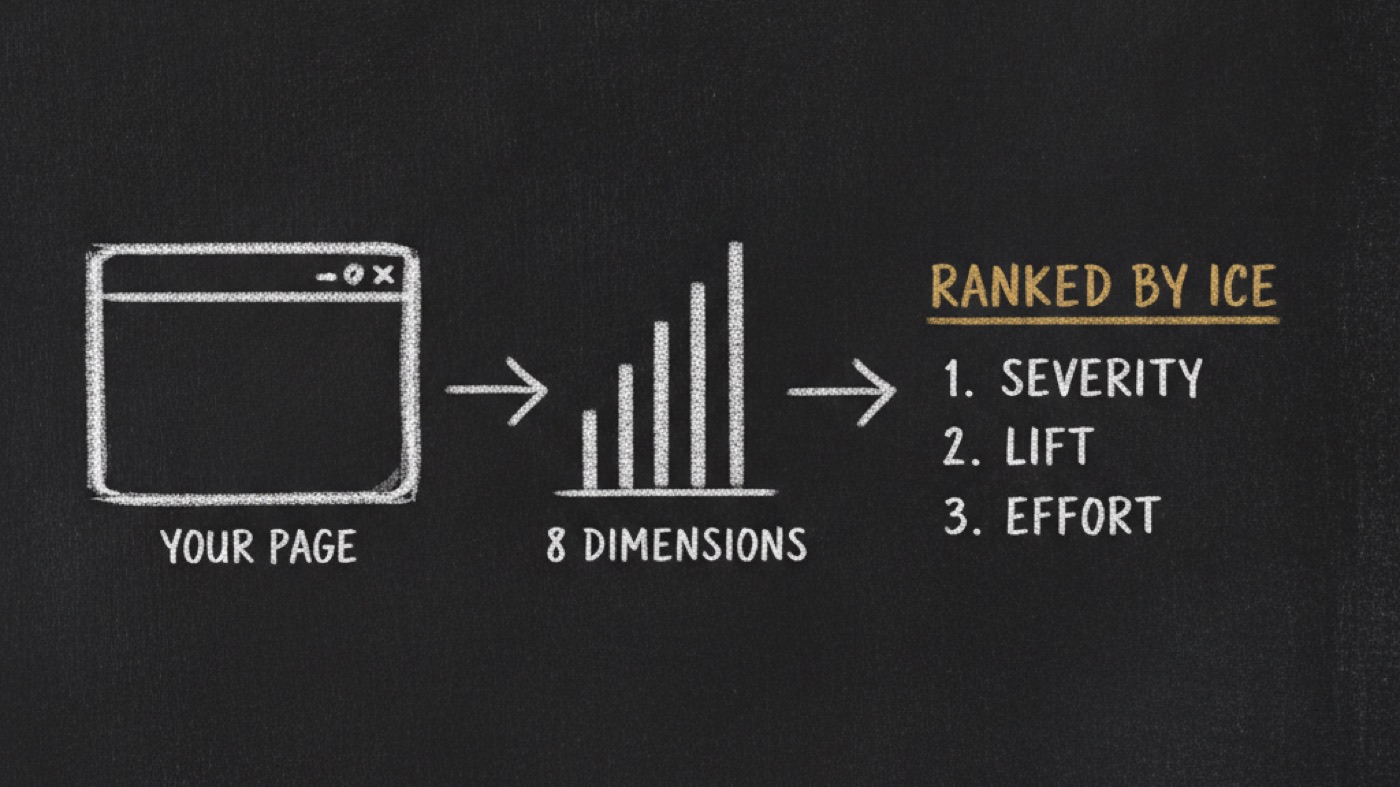
Significance and causal-overreach, 10 checks. Both pass or it is not a verdict
Banks 50-80% of the raw lift, never the test number itself
A lost verdict rolls back through SpiderPublish, it does not just get noted
Feeds cro-audit's baseline so the next audit starts from a checked number
No PostHog and no GA4 means wire analytics first, not guess
Videos1 video
DemoCRO Optimizer · Demo video
Demo · SpiderMediaArticles about CRO Optimizer2 articles
My best CRO win was +25%. The retest said minus 14%.
 opvs.ai22 Jul 2026
My best CRO win was +25%. The retest said minus 14%.
A quiz-flow test came back +25%. I wrote it down as a win. Someone re-ran it later and got minus 14%. Nothing broke — I just treated one run as a fact. Here are the four numbers that changed how I read every result, and the skill I built to stop a CRO program from believing its own wins.
Videos1 video
DemoCRO Optimizer · Demo video
Demo · SpiderMediaArticles about CRO Optimizer2 articles
Showing all 2
SKILL.mdthe file your agent reads
SKILL.md loads when you open this tab.
What's new3 releases · newest first · from the package's CHANGELOG
v0.1.32026-11-04Latest
- Added the captioned launch explainer film (`media.demo_video_url`) to the marketplace listing.
v0.1.22026-07-22
- Tier moved `internal` → `beta` and `skills[0].visibility` → `public`. The package was
  published in June and has been invisible in the catalog ever since; it is now installable
  by customers.
- Added the marketplace card: `media.hero_image_url` + 3 screenshots, plus `marketing.author`,
  5 feature bullets and a first-person `long_description`.
- Declared `type: skill`.
- Cleaned the published bundle — `BRIEF.md`, `_archived-umbrella-brief/` and `tests/` are no
  longer shipped to customers.
v0.1.02026-06-17 (unreleased
- Initial guidance-only release. The closed-loop CRO refiner — third skill in the CRO chain.
- 3 reasoning methods: `analyzeTestOutcome`, `updateAuditBaseline`, `generateNextHypothesis`.
- 6 references, 5 recipes (weekly-review / post-test-learning / baseline-refresh / kill-the-test /
  escalate-to-redesign), 18 test-outcome registry cards, 12 learnings.
- 2 enforcement scripts: `verify-significance-claims.mjs` (significance gate) +
  `lint-causal-overreach.mjs` (causal-overreach gate).
- Composes `@posthog/ai-plugin` (measure + delegate significance diagnosis), `@spideriq/spiderpublish`
  (provenance + act), and the cro-audit/cro-actions chain.
- Verdict vocabulary aligned to PostHog's `experiment-end` conclusion enum.
- Coordination across all four OPVS surfaces (agentboard / agentdocs / agentmemory / opvs-protocol).
- EN-first. Compliance-aware (never banks an unsubstantiated/REACH-CLP claim lift).
Showing all 3