I watched another outbound batch bounce before noon. Everything in my sequence looked sharp on paper. My targeting filter was narrow. My copy was plain and direct. Still, the bounce notifications piled up fast. People had left those jobs months ago. Half the company domains redirected or sat dead. That was not an email writing problem.
Renting a static lead database means buying decay.
Every big B2B database starts rotting the day someone exports a row. Ten thousand other sales teams rent that exact same table. They hammer the same stale inboxes every week. You pay for rows that your competitors already burned. When I started out, I thought I only had two choices. Either I wired map scrapers, site crawlers, and email checks myself. Or I paid a list agency per spreadsheet. Then I looked closer at what the agency sent me. I paid a markup for the same aged database export. Worse, blind list buys kept charging me for companies already in my CRM.
Give the whole discovery pipeline to your agent
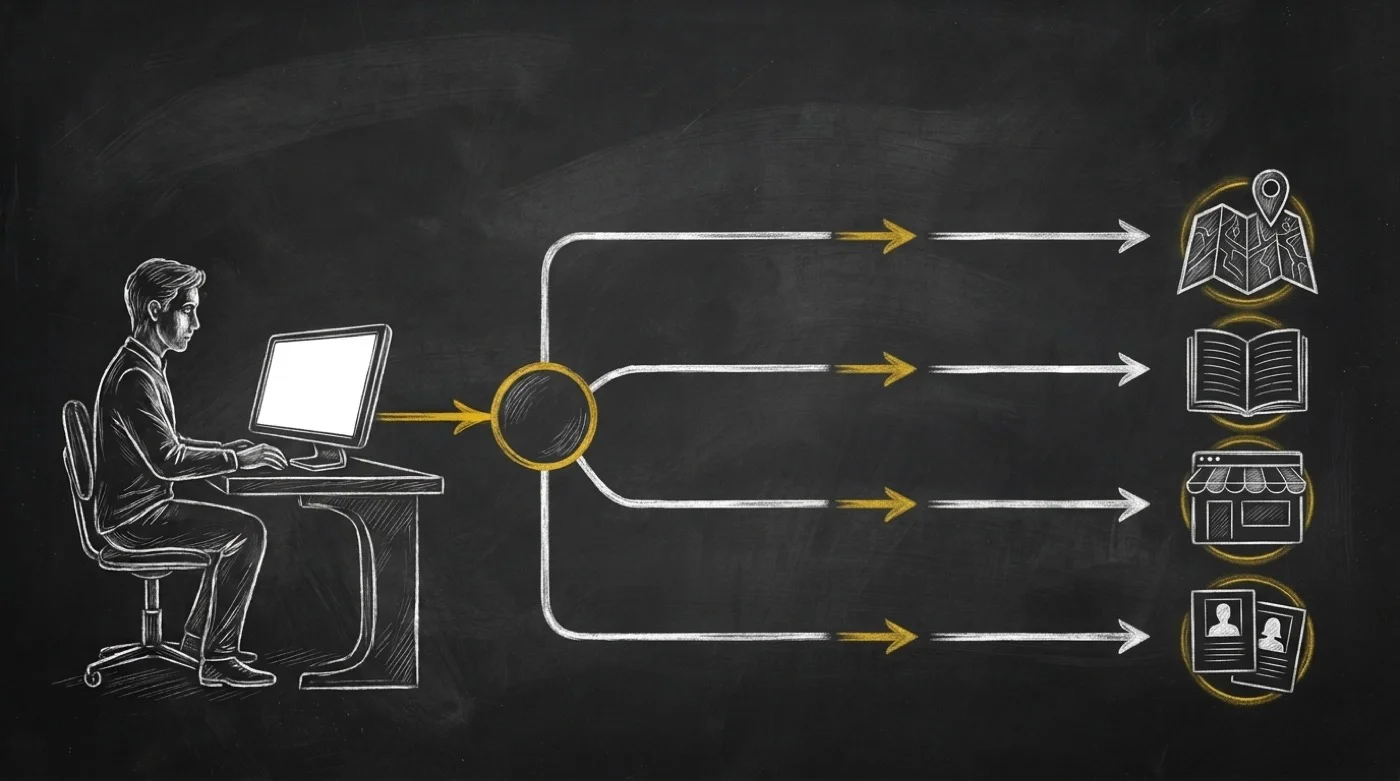
I built @spideriq/spiderflows on OPVS so your agent runs discovery live on SpiderIQ. You stop renting last year's spreadsheet. Instead, you hand one plain brief to your agent. I recorded a 57-second chalkboard walkthrough on the SpiderFlows skill page so you can watch the full loop.
One request over HTTP, CLI, or MCP starts chained server-side workers. My goal was keeping raw scrape noise out of your chat window. SpiderIQ runs the heavy crawling across 470 parallel worker slots on 11 VPS. Your agent polls or streams progress while it handles your next task. When the run finishes, normalized rows land inside IDAP. I read back clean businesses, domains, contacts, emails, and phones from one place.
Four live flows replace five stitched tools
Most teams glue five brittle tools together just to build one clean list. I packed those recurring revenue pipelines into one skill with shared guardrails.
Local and regional lead campaigns (
searchLeadsandcreateCampaign). Sold asleadSearchandlocalSeo, this chain starts on Google Maps. Next, it crawls each live website for emails, phones, socials, and team pages. When a site hides its email, plan-gated social enrichment checks public handles. Every address runs through live SMTP verification. Optional VayaPin or SmartLead export runs at the end. I test one city first. Then you can fan out across regions and population bands. For U.S. ZIP campaigns, I scope one state at a time withlist_regions. Country-wide U.S. ZIP runs hit the 10,000-location cap and get rejected for safety.Wholesale bulk sourcing and free agency directories (
sourceLeadsBulk). When I want breadth in a single purchase, bulk mode deduplicates up front. It runs across queries and locations through Outscraper or Apify. Each deduplicated lead then enters its own crawl and verify chain. Bulk mode has no per-location retry. I pick it when flat dedup matters most. For B2B agency outreach, sourcesortlistreads a public directory of agencies. It spans marketing, design, and dev firms across 109 services, 26 industries, and 21 countries. Reading Sortlist is free at the source. I only spend credits on website crawling and email verification. VayaPin republication is refused on Sortlist records.Re-enriching leads your workspace already owns (
sourceLeadsInternal). Buying a second copy of a lead I already own wastes budget. When I ask about existing leads, my agent writes a validated filter AST. It callscountCorpusLeadsfor free before spending a cent on missing websites or emails. You can also re-enrich an older campaign that never ran verification.Full Company Intel briefs and LinkedIn rosters (
researchCompanyandresearchCompaniesBatch). Give your agent one company name, or a batch of up to 50 companies. The pipeline chains Perplexity domain lookup, SpiderSite crawling, and UK, U.S., and EU registry filings. Then it pulls LinkedIn teams and verifies every email. Separate LinkedIn modes enrich profile URLs, search by title, or pull employee rosters. For direct offers,applyFunnelTemplateforks a validated checkout and upsell funnel landing a Stripe order.
Budget gates and honest clocks before a credit spends
Letting an autonomous agent launch multi-city scrapes without a cost check is dangerous. An unscoped country filter in Germany alone fans out to 1,733 locations. That is why I made the pre-flight /estimate call free and read-only across SpiderFlows. Before my agent submits a run, it reads exact total_locations and total_billable_jobs per stage.
Version 0.13.x also quotes expected run duration from your account's jobs_per_hour quota. A 21,000-record batch at 500 jobs per hour takes 42 hours. Now I see that clock before I confirm. When a quota cannot be resolved, the API returns hours: null and says so verbatim. My agent never invents a fake timer. Multi-hour enriching runs stay open while location rows settle, up to a 24-hour ceiling.
What changes when you drop static lists
My outbound workflow feels completely different once stale spreadsheets leave the building. I no longer spend Mondays cleaning CSV exports or burning sender domains on dead inboxes. I tell my agent which market or company list I want. It checks my existing corpus first, quotes the exact job count, and streams fresh records into IDAP.
Watch the 57-second launch film and inspect the recipes at opvs.ai/skills/spiderflows, or follow updates on the OPVS changelog.
Live on the marketplace as @spideriq/spiderflows.