Video Analyst
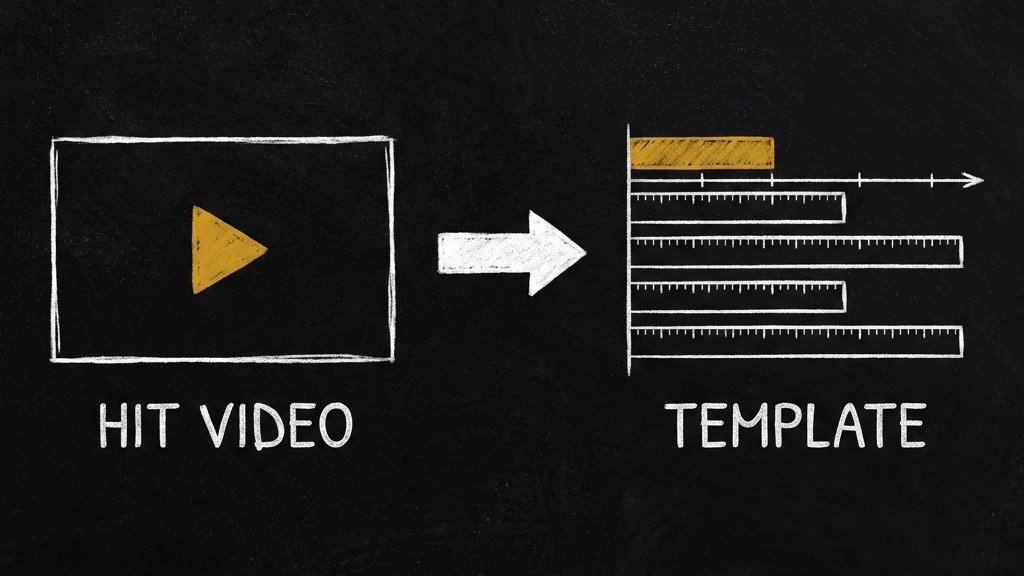
Watch a video, emit a reusable TEMPLATE — not a summary. Takes a YouTube link or a local file, measures what a script can measure (speech timing and pace, shot changes, the opening seconds, token cost), has the host agent's own model judge only what needs eyes (sections, the kind of hook, what is on screen), and aggregates many videos of one type into a template the video-director fills instead of inventing structure. Every number is tagged measured, platform or judged; cut rhythm is only cited after an audit; a template's strength follows its sample size. Five gates print PASS/FAIL with numbers. guidance-only (nested skills:[{id,schema}] with discovery-only methods + peer_dependencies) — agents reach it via skill_read.
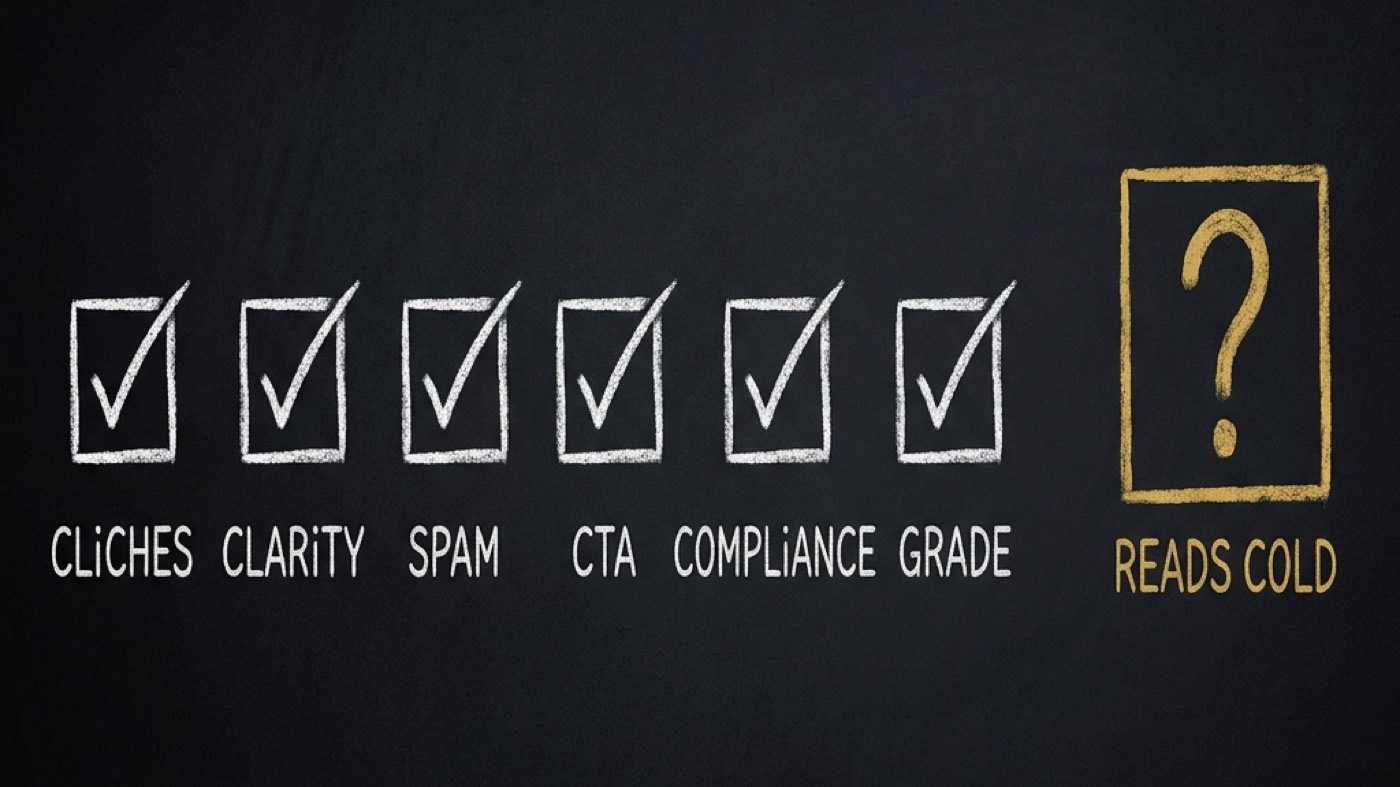
I built this because every video I planned started from a blank page, while the videos that work sit on YouTube with their structure in plain sight. Give your agent a YouTube link or a local file and it returns a template, not a summary. Scripts measure the timing: when the first word lands, the voice-over pace, the shot changes and the image-token cost of the run. Your agent's own model judges only what needs eyes, and cites the frame it used, so every number is labelled measured, platform or judged. Cuts are checked, not trusted. On a promo with 9 known cuts, the documented scene thresholds found 0 and the bundled detector found all 9. On real footage raw candidates were right 16 to 80 percent of the time, so no shot rhythm is cited until each cut is confirmed. Linear's 4-minute intro came back as 12 timed sections at 168.7 words per minute, for 28,832 image tokens. Its director_input block goes straight into @di-atomic/video-director. It runs on the model your IDE already uses and never calls one itself.
Features5
Turn a YouTube link or a local video into timed sections, pace and opening rules.
Tag each value measured, platform or judged, with the frame behind every judgment.
Confirm each detected cut from four frames and print the precision it reached.
Mark a template single, emerging or established by how many videos back it.
Print each run's image-token cost, recomputed from the actual frames.
Videos1 video
DemoVideo Analyst · Demo video
Demo · SpiderMediaArticles about Video Analyst2 articles
Stop guessing video structure. Your agent measures it from a proven hit
 opvs.ai24 Sep 2026
Stop guessing video structure. Your agent measures it from a proven hit
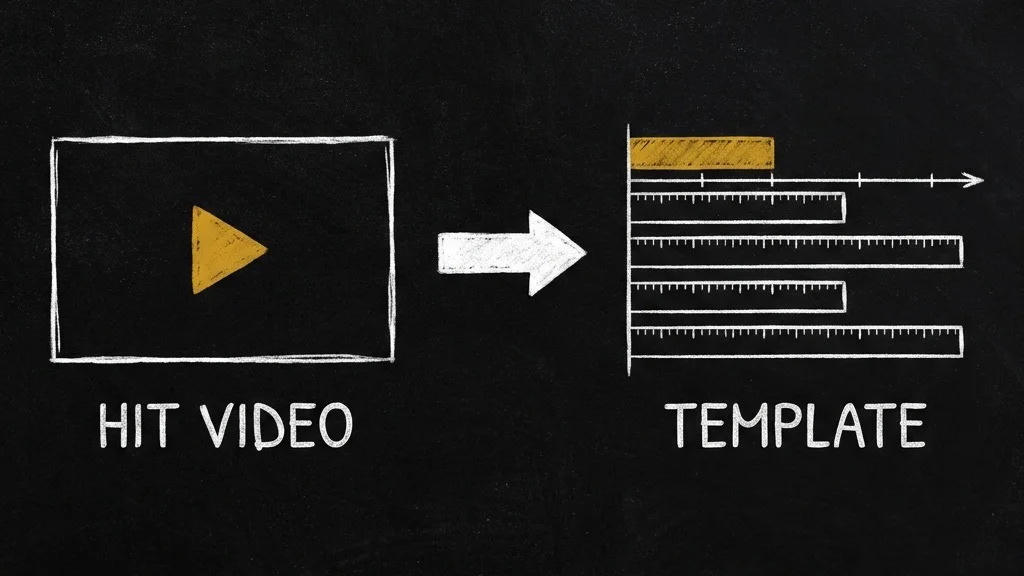
@di-atomic/video-analyst is live. Give your agent a YouTube link or a video file and it hands back a reusable template: timed sections, voice-over pace, opening rules and checked shot rhythm that the video-director fills.
Videos1 video
DemoVideo Analyst · Demo video
Demo · SpiderMediaArticles about Video Analyst2 articles
Showing all 2
SKILL.mdthe file your agent reads
SKILL.md loads when you open this tab.
What's new3 releases · newest first · from the package's CHANGELOG
v0.1.22026-11-10Latest
Marketplace listing update: added the launch explainer film (`media.demo_video_url`). No code, schema, copy or guidance changes; hero and screenshots unchanged from 0.1.1.
v0.1.12026-09-24
Propagation patch. No change to the method, the scripts, the gates or the `observation@1` /
`template@1` shapes.

### Added

- **Marketplace card media.** `media.hero_image_url` plus three screenshots (one video at two
  speeds, the peer chain into video-director, the sample-size tiers), rendered once and reused
  across the launch blog, both listing surfaces and the card.

### Changed

- **Card copy rewritten to the card rules.** `marketing.long_description` is first person
  throughout (the 0.1.0 text said "we" and "our"), 180 words, with its numbers as numerals and the
  Director named as the consumer. Five feature descriptions, each 90 characters or fewer and
  verb-led.
- **README in first person.** Two "our" phrases in "Why it exists" now read "my".

---
v0.1.02026-09-24
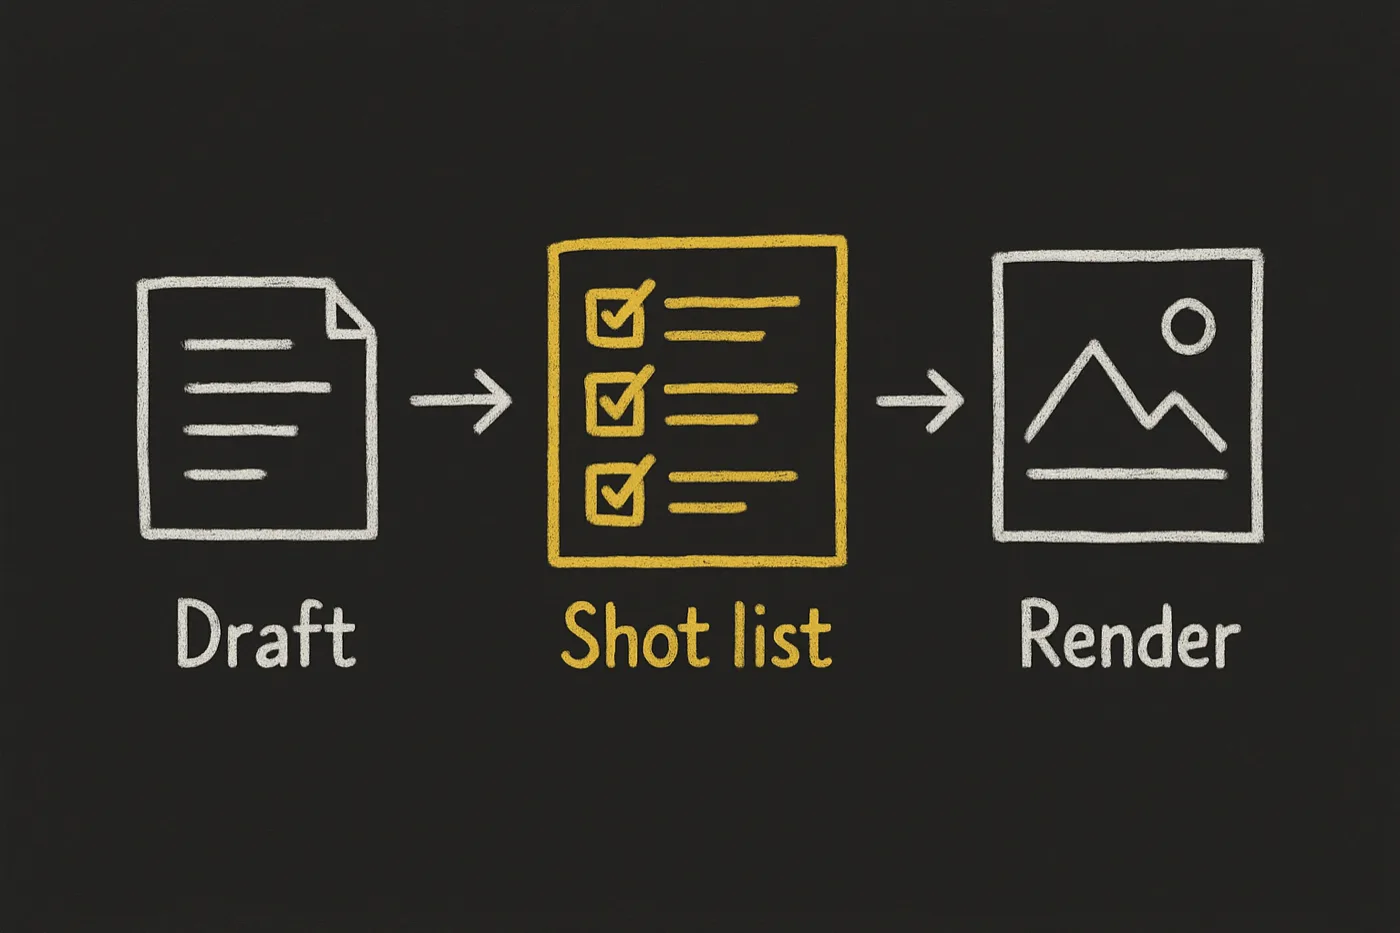
First release. Guidance-only: the agent runs the bundled scripts in its own shell and reads frames
with its own model, following `SKILL.md` (reached via `skill_read`). No backend, no HTTP-bound methods.

### Added

- **Observation record** (`observation@1`) — one video, every number tagged `measured`, `platform` or
  `judged`, with provenance, audit and token cost.
- **Template** (`template@1`) — medians with order-statistic ranges, strength by sample size
  (single · emerging · established), opening rules with `k/N` and evidence, and a `director_input`
  block in the exact shape `@di-atomic/video-director` declares.
- **Shot detection** — a stdlib perceptual-hash candidate detector (abrupt + gradual passes, three
  presets), 4-frame confirmation strips, and an audit computed from the agent's classifications.
- **Five gates** — `verify-observation`, `verify-template`, `verify-cuts` (control test),
  `estimate-frame-tokens`, `verify-coordination`.
- **Four recipes**, four references, 25 learnings, and a registry of 18 measured public videos, 2
  ground-truth controls (Control A ships its 640×360 render), a worked template from one real video
  (explainer, presenter + screen), reference tables and both schemas.
- **Honest run cost** — `token_cost` counts the confirmation sheets as well as the frames, and
  `estimate-frame-tokens` recomputes both (a 4-minute screencast: 6,897 + 21,935 = 28,832).
- **Frames the judgments need** — frame-accurate confirmation strips (the two frames the detector
  compared), opening probes at 0.5 / 1.5 / 2.9 s, and gap fills so no stretch of screen recording
  goes unseen.
- **Director-ready timings** — repeated sections keep their own lengths, section edges snap to cuts
  within 2 frames, and `director_hints` carries per-section pace when a video has more than one.
- A manual caption track is preferred over an auto-generated one (ScrapeCreators returns the first
  listed track, often the ASR one).
- Frame and caption extraction adapted from an MIT-licensed open-source extractor (licence and change
  list ship in `scripts/watch/`): caption language picked from the video's own tracks, metadata and
  captions fetched separately, user-supplied cookie passthrough, Whisper keys never read from a
  workspace `.env`.
Showing all 3