Thumbnail
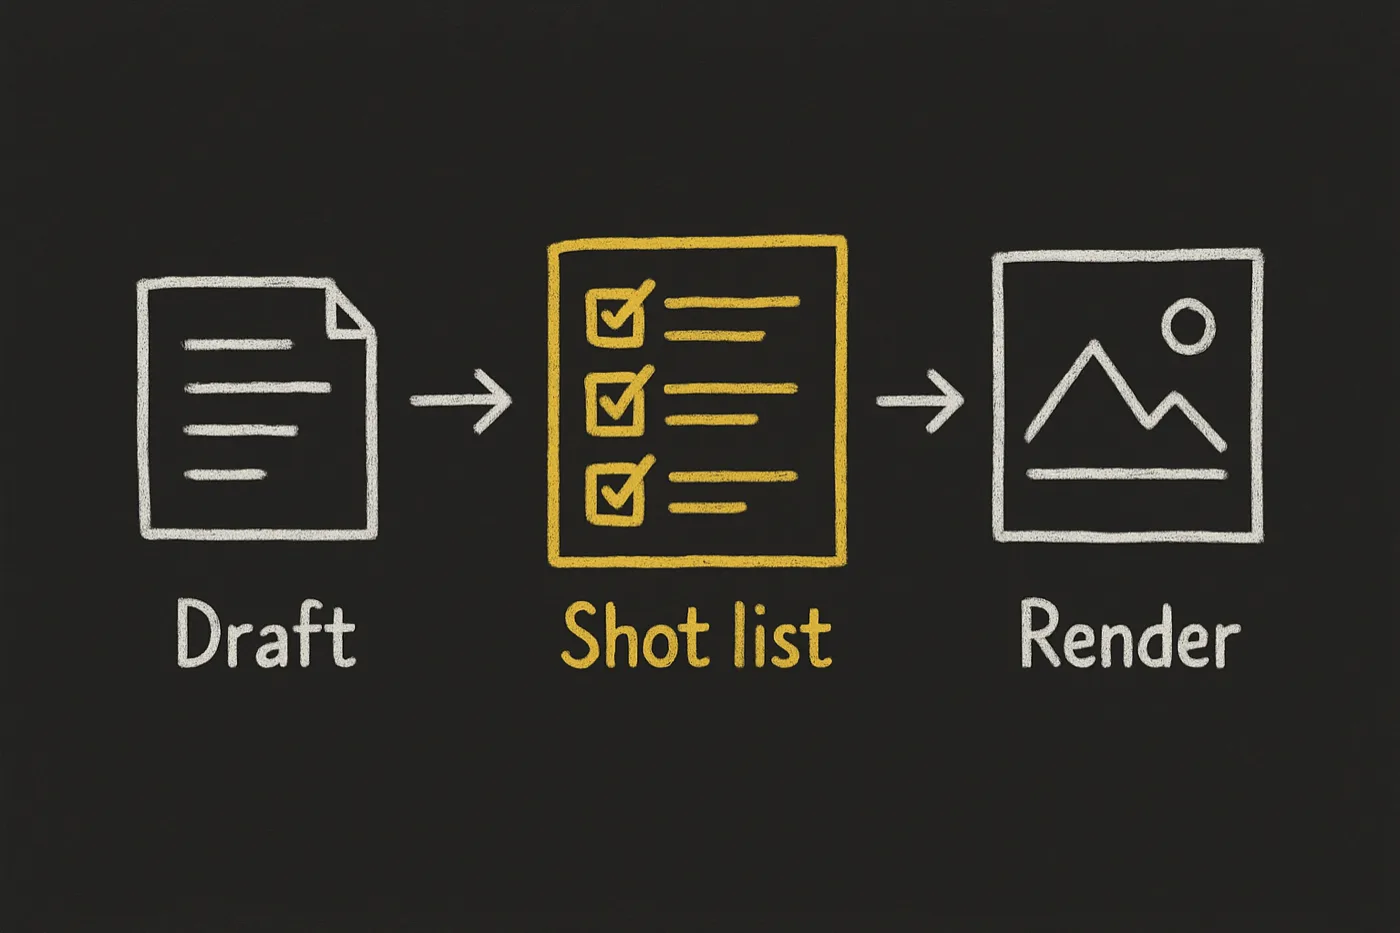
The click image for a video, graded where it is shown smallest. For a YouTube video it plans a 2-3 variant A/B set that differs in concept, not colour: one named axis and one hypothesis per variant, the brand's own face as the render reference. For a Short, Reel or TikTok it makes one cover. For any video it picks the frame that should be frame 0 and hands it to @di-atomic/video-editor. Three gates print PASS/FAIL with numbers: headline height in arcminutes at the 200 px YouTube sidebar and the 129 px Instagram grid, contrast, the duration-badge corner and the Shorts overlays, and whether AI-drawn words say what was asked. A host without OCR gets UNVERIFIED, never PASS. 5 recipes, 37 registry items, 5 reference procedures. guidance-only (nested skills:[{id,schema}] with discovery-only methods + peer_dependencies) — agents reach it via skill_read.
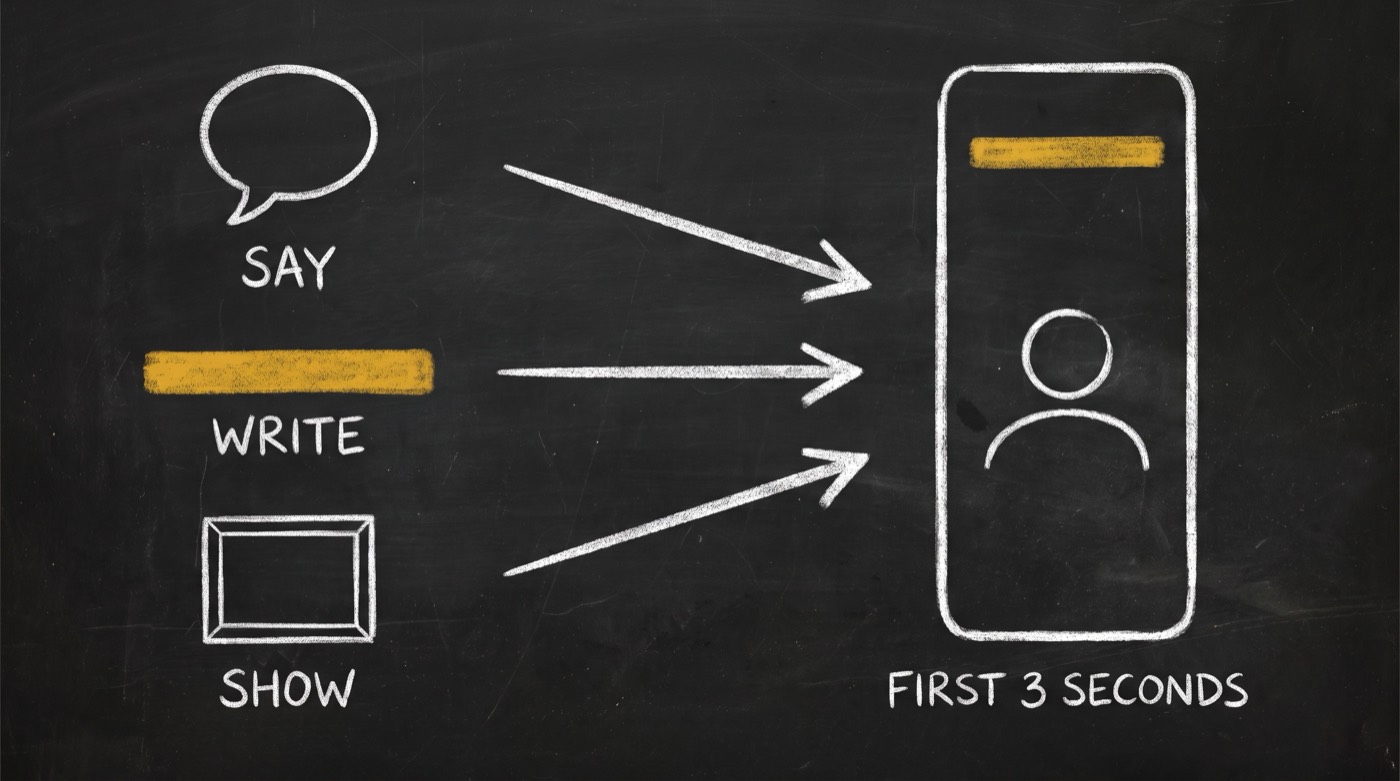
Your thumbnail is judged 200 pixels wide. That is how YouTube's sidebar shows it in a laptop window, and Instagram's profile grid shows a cover 129 pixels wide. I ran 941 thumbnails from AI-tool, SaaS and B2B-marketing channels through the same checks: about 1 in 10 had nothing readable at 200 px, and about 30% put words where the duration badge sits. So this skill does two jobs. It keeps every image readable where it is small: a headline of 16 arcminutes or more, contrast of 4.5:1 or better, nothing under the badge or the Shorts overlays, and AI-drawn words read back before anyone trusts them. And it makes the A/B set test ideas. A recoloured copy scored a fingerprint distance of 0 to 1 against its original, while 95% of real pairs scored 20 or more, so a set passes only when every pair clears 16. It also picks the poster frame, and @di-atomic/video-editor bakes it as frame 0. @di-atomic/youtube-content-creator writes the title and @di-atomic/media-generator renders the images.
Features5
Checks headline height at the 200 px YouTube sidebar and the 129 px Instagram grid.
Plans 2 to 3 variants with one idea and one hypothesis each, then proves they differ.
Reads AI-drawn headlines back with OCR and typesets them when they fail.
Keeps a cover's words clear of the Shorts overlays and the 3:4 grid crop.
Picks a settled, non-black poster frame and hands it to video-editor to bake.
Videos1 video
DemoThumbnail · Demo video
Demo · SpiderMediaArticles about Thumbnail2 articles
Your agent builds the 3 thumbnails for YouTube's A/B test
 opvs.ai24 Sep 2026
Your agent builds the 3 thumbnails for YouTube's A/B test
@di-atomic/thumbnail is live. Your agent plans two or three YouTube thumbnails that test real ideas, checks each one reads at the 200-pixel sidebar, makes covers for Shorts and Reels, and picks the frame your video opens on.
Videos1 video
DemoThumbnail · Demo video
Demo · SpiderMediaArticles about Thumbnail2 articles
Showing all 2
SKILL.mdthe file your agent reads
SKILL.md loads when you open this tab.
What's new3 releases · newest first · from the package's CHANGELOG
v0.1.22026-11-10Latest
Marketplace listing update: added the launch explainer film (`media.demo_video_url`). No code, schema, copy or guidance changes; hero and screenshots unchanged from 0.1.1.
v0.1.12026-09-24
Marketplace card only. No change to the skill, its scripts or its layers.

### Added

- **Card media.** A hero and three illustrated panels (graded at 200 px · the peer chain · recolour vs real ideas),
  hosted on media.spideriq.ai.

### Changed

- **Card copy.** The long description leads with what the buyer gets and fits the 150–200 word card range;
  every feature description is 90 characters or fewer.

---
v0.1.02026-09-24
First release. Guidance-only: nested `skills:[{id, schema}]` with five discovery-only methods and four
coordination peers.

### Added

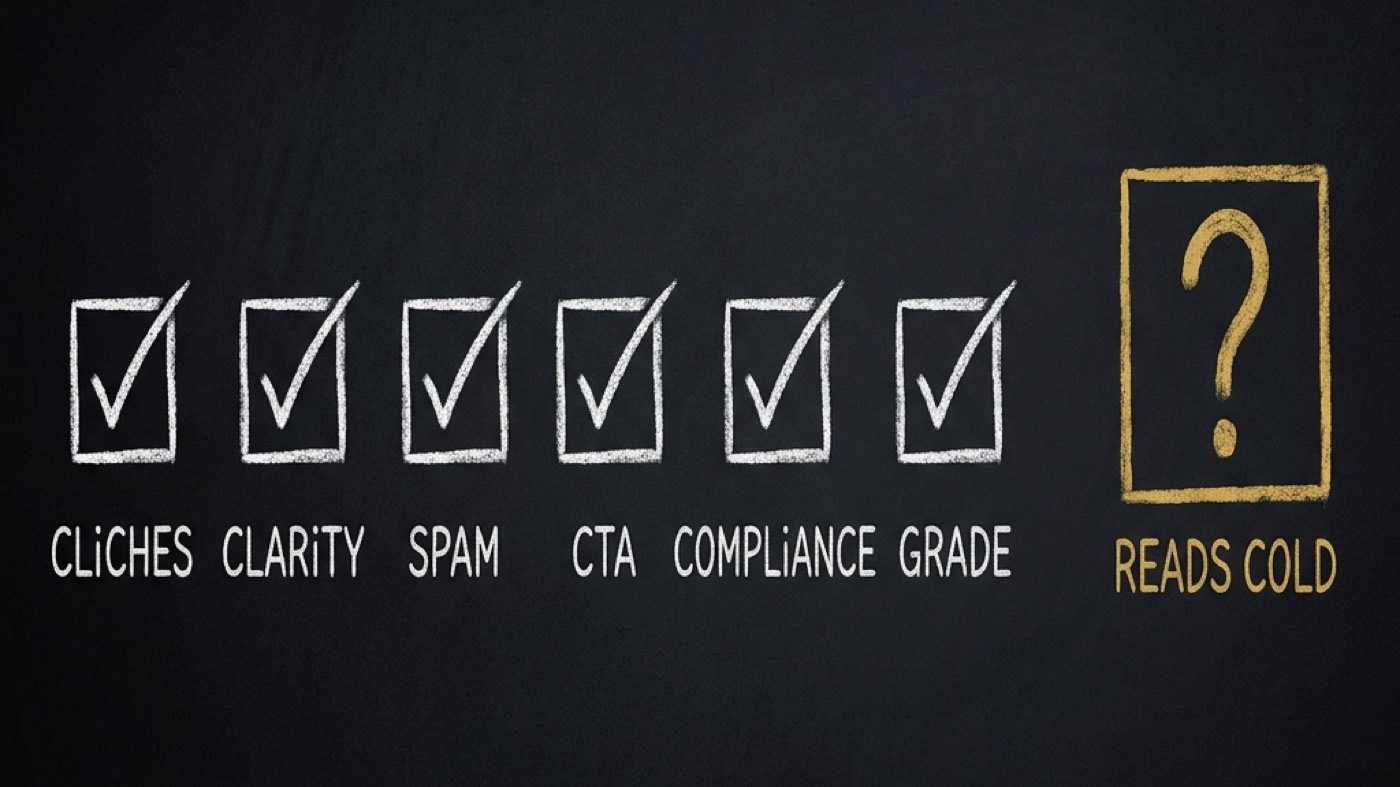
- **Three gates that print PASS / FAIL / UNVERIFIED with numbers.** `verify-thumbnail` grades one image at
  the smallest display it will get (200 px YouTube sidebar, 175 px Shorts grid, 129 px Instagram grid):
  headline height in arcminutes (ANSI/HFES 100), contrast (WCAG 1.4.3), the duration-badge corner and the
  Shorts / grid bands, and whether AI-drawn words say what was asked. `verify-variant-set` requires 2–3
  variants that each lead with one idea and look different (dHash ≥ 16). `pick-poster-frame` rejects black, cut and unsettled
  frames and writes a contact sheet.
- **`compose-thumbnail`** — typesets a headline over a picture at the size the smallest display needs,
  from a resolved font file whose glyphs are all checked; refuses RTL text on an ffmpeg without libfribidi.
- **5 recipes, 5 procedures, 37 registry items** (platform contracts read 2026-09-24; display sizes and
  overlays measured on youtube.com and instagram.com; 16 niche exemplars as links + numbers), **22
  learnings**.

### Known limits

- The TikTok grid size is an inference: TikTok served a CAPTCHA to the measuring browser.
- The "settled" threshold (SSIM ≥ 0.90) is provisional until calibrated on more real renders.
- V3 reads layout, not meaning. A variant that changes one element in place (only the words, or only the
  expression) scores 0–12 and fails, so every variant must look different. Two real ideas that share a
  light/dark layout can fail too (1.9 % of real same-channel pairs): move the words or the dark areas.
- The AI-drawn words path (a media-generator render, then read back) has not yet run end to end on a real
  render. The read-back gate itself is tested; typeset headlines are exact.
- OCR read-back is unreliable for Cyrillic and absent for Hebrew — both are typeset.
- Slack / X / Discord using frame 0 rests on a single source.
Showing all 3