CRO Audit
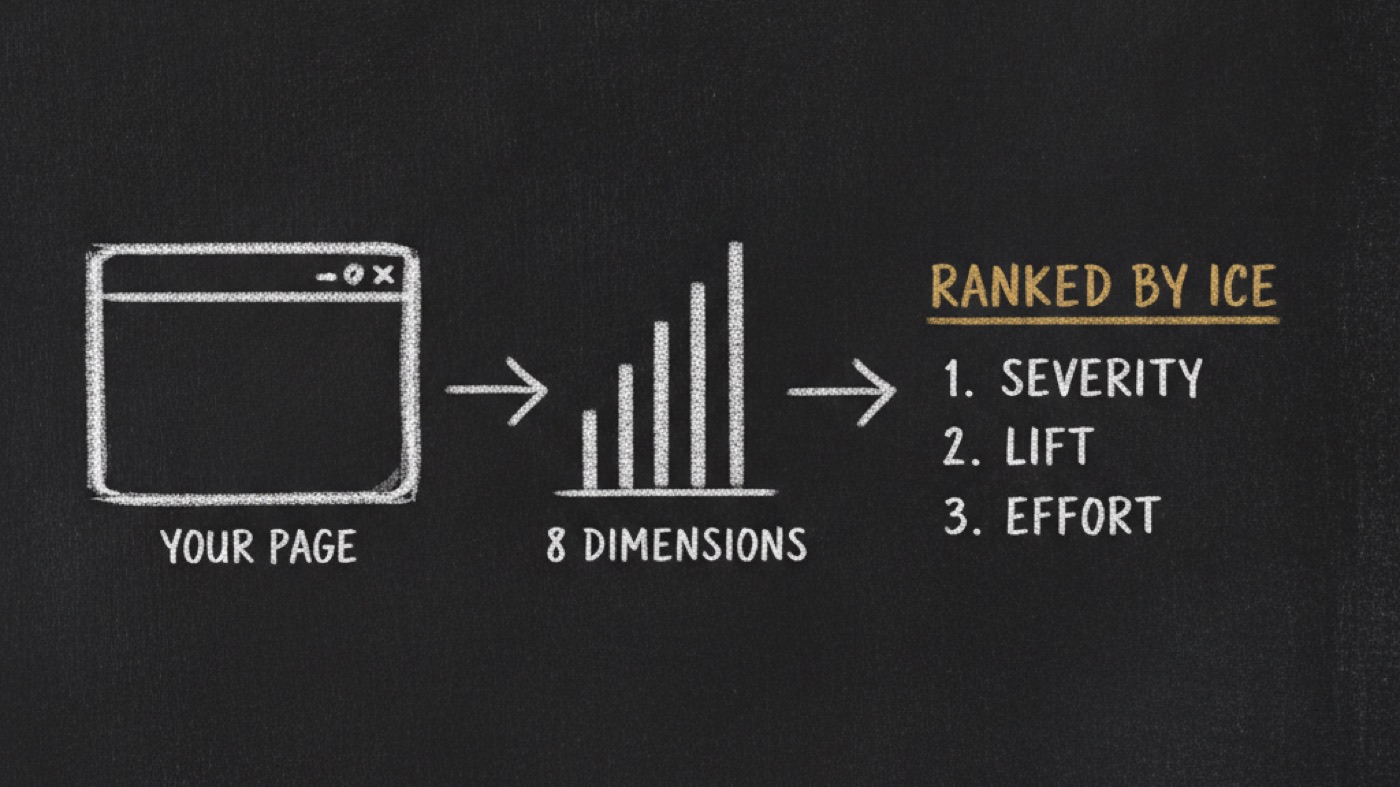
Diagnose why a live page isn't converting. Audits a landing page, pricing page, signup/checkout flow, blog post, docs page, homepage, or mobile experience across 8 CRO dimensions and returns a ranked finding list (severity × lift ÷ effort) where every finding names a specific element AND cites a real benchmark — never a platitude. Re-audit a funnel you already audited and it returns three-state verdicts and a delta instead — STILL BROKEN, FIXED, or UNKNOWN, never a guess. Backed by 60 metric-bearing teardown-evidence cards + 9 recipes + 5 enforcement scripts. GUIDANCE-ONLY: the agent's own LLM does the reasoning per SKILL.md; state persists via the upstream OPVS coordination skills declared as peers. Diagnoses only — routes fixes to SpiderPublish (block edits / sys-* CRO components), copy-engine and section-designer.
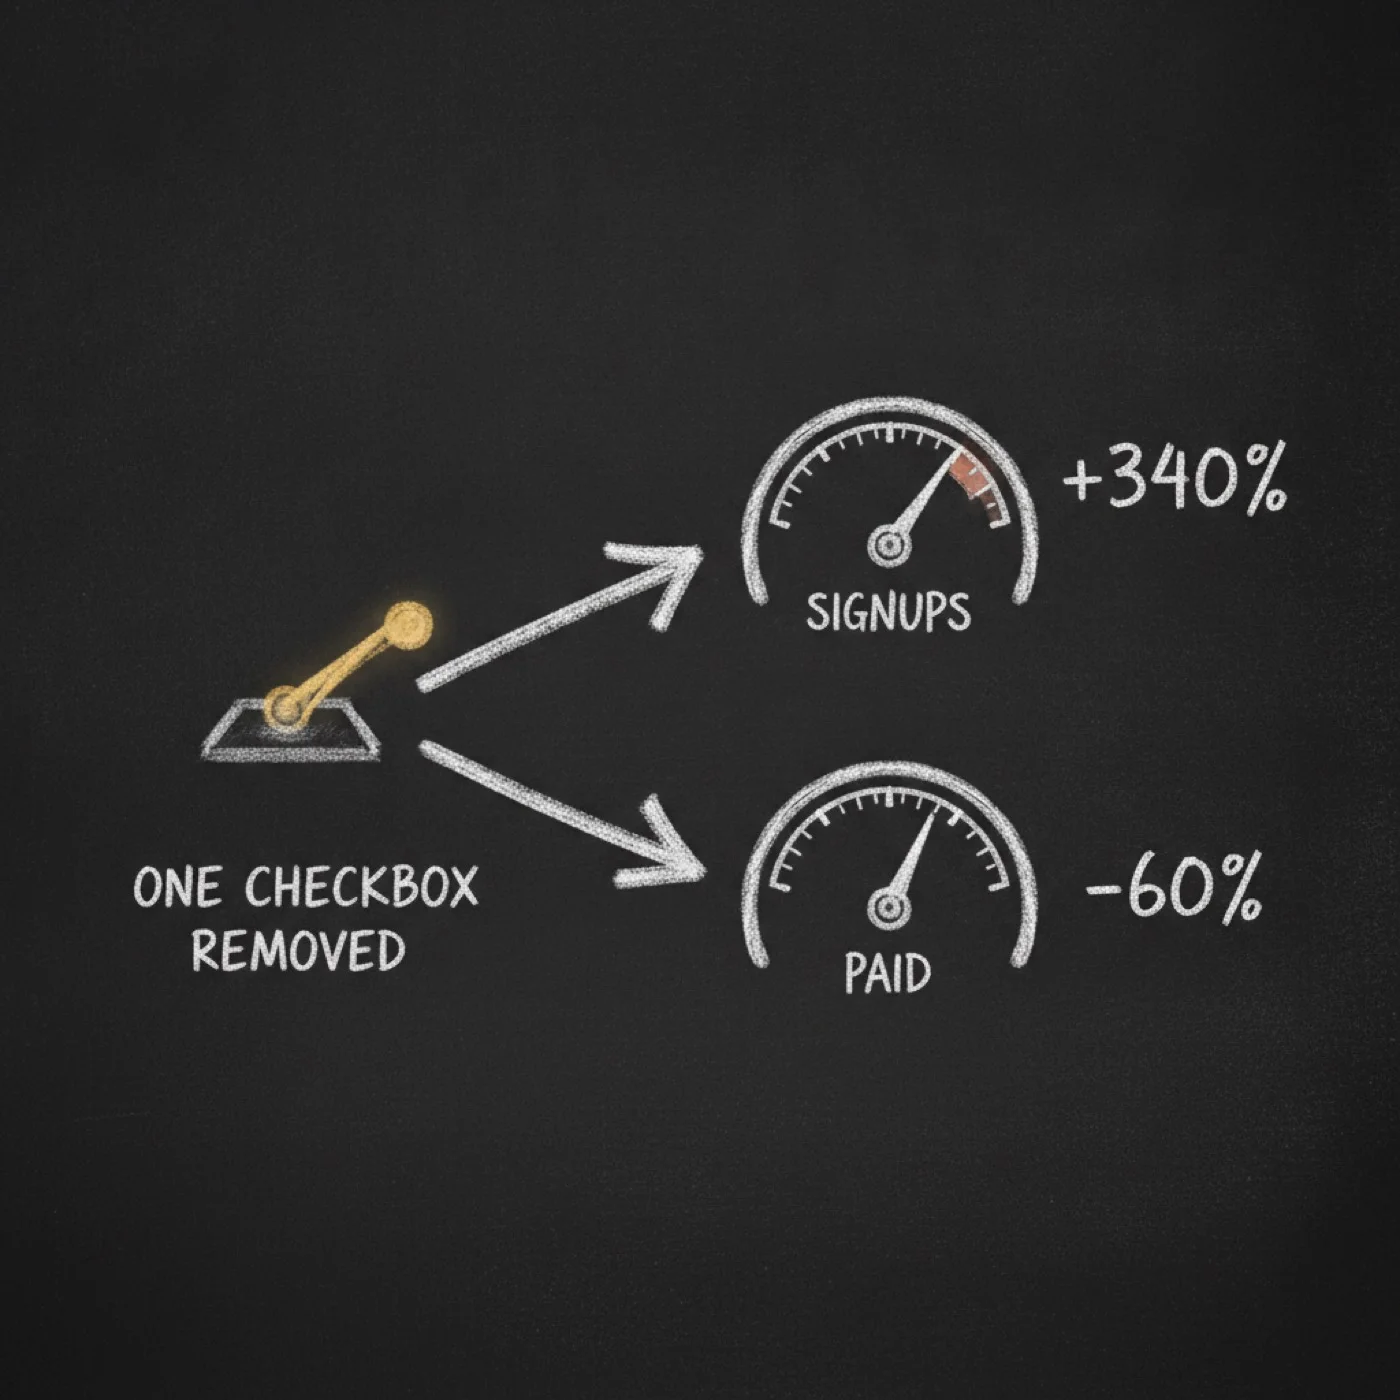
I built this because my first CRO auditor was useless. It scored well on every internal check I had and still handed me "add social proof" and "make the CTA pop" — advice that is true of pages in general and unfalsifiable about yours. Generic best practice is survivorship bias: what worked in someone else's context, abstracted until every detail that made it true is gone. Three numbers convinced me. A founder removed the credit-card gate from his trial and got 340% more signups with 60% less trial-to-paid. Social login lifts consumer signup 20-35% and reduced conversions for a B2B tool. The same trust badge has measured anywhere from -5% to +75% purely by placement. So cro-audit scores all 8 dimensions or fails, ranks findings by severity times lift divided by effort, and runs scripts that reject any finding which does not name a page element and cite a real benchmark with a source. Re-auditing taught me the second half. Split a funnel by where it writes, not by page, and most of it re-runs for free. Then be honest about what you measured: I once read a claimed test account as a dead funnel and filed a critical finding I had to withdraw, and I watched one unchanged page measure 848ms and 3032ms minutes apart. So a regression run answers STILL BROKEN, FIXED or UNKNOWN, and UNKNOWN is never a pass. It diagnoses only. Fixes go to SpiderPublish, copy-engine and section-designer.
Features6
Score all 8 CRO dimensions or the audit fails
Every finding names a page element and cites a benchmark
Rank fixes by severity times lift divided by effort
Refuse fake urgency, fake scarcity and fake social proof
Flag regulated-page claims as exposure, not conversion wins
Split a funnel where it writes; re-test the free half and report the delta
Videos1 video
DemoCRO Audit · Demo video
Demo · SpiderMediaArticles about CRO Audit2 articles
340% more signups. 60% less paid revenue. One removed checkbox.
 opvs.ai22 Jul 2026
340% more signups. 60% less paid revenue. One removed checkbox.
A founder removed the credit-card gate from his trial signup and got 340% more signups and 60% less paid conversion. He had followed the advice. That is the problem with CRO best practice, and the reason my auditor now fails its own build when it produces a platitude.
Videos1 video
DemoCRO Audit · Demo video
Demo · SpiderMediaArticles about CRO Audit2 articles
Showing all 2
SKILL.mdthe file your agent reads
SKILL.md loads when you open this tab.
What's new5 releases · newest first · from the package's CHANGELOG
v0.2.12026-11-04Latest
- Added the chalkboard explainer launch film (`media.demo_video_url`) to the marketplace listing.
v0.2.02026-08-11
- **New surface: funnel regression.** `recipes/audit-funnel-regression.md` answers "is what we found last time still broken" instead of "why is this page weak" — it re-tests known defects and reports the delta, not a fresh scorecard.
- **New method: split a funnel audit by mutation boundary, not by page.** `references/funnel-mutation-boundary.md` — find the last step before the funnel writes; everything upstream re-runs at zero cost, only the tail spends a fixture. On the funnel this came from, the boundary sat at stage 5 of 6, which turned a one-shot manual teardown into something cron-able.
- **Three-state verdicts.** STILL BROKEN / FIXED / **UNKNOWN**. UNKNOWN is never a pass — a binary check silently converts "I couldn't tell" into "it's fine".
- **New script `scripts/verify-verdict-integrity.mjs`** (5th enforcement script). FAILs on: a verdict rendered where the sample spread exceeded the threshold under test, a noisy metric verdicted from a single sample, a check set with zero controls, and fixture state not asserted before the first check.
- **2 new learnings** (15 total): a converted fixture reads the funnel as broken (a critical finding filed on an already-claimed test account, later retracted); a noisy metric needs agreement, not an average (LCP on one unchanged URL measured 3032 / 1100 / 848 / 2272 ms against a 2500ms threshold).
- Upstream MIT attribution consolidated from `source/` into a root `NOTICE.md` — same obligation, carried at bundle root.
- **Still guidance-only, by decision.** The live prober stays client-side: it generates load, pollutes analytics, can trip a WAF, and its destructive phase consumes a real account. All 5 scripts check the agent's own output; none reach into a client's production system.
v0.1.22026-07-22
- **Now customer-visible.** 0.1.1 shipped at `tier: internal` with `skills[0].visibility: internal`, which kept the package hidden on the marketplace from 2026-06-22. Both corrected to `beta` / `public`.
- Added the marketplace card asset kit: hero + 3 screenshots (`media:` block), a first-person `long_description`, and 5 feature bullets.
- Added `type: skill` to the manifest.
- Bundle pruned to the canonical shipping set. Upstream MIT LICENSE notices + `source/README.md` provenance retained; bulky upstream working code dropped.
- Corrected the ICE formula in the description from `severity × lift × effort` to `severity × lift ÷ effort`, matching SKILL.md.
- Dropped the `cro-actions` handoff claim from the description — that sibling is not shipped yet.
v0.1.12026-06-22
- Re-published with the nested `skills:[{id, schema}]` bundle shape so `skill_read` resolves.v0.1.02026-06-17
- Initial greenfield build (v2.1 format, guidance-only). Supersedes the retired backend-DOING "v3" design (schema.yaml + provider_config — the 404-trap).
- 8-dimension CRO scoring (value_prop, cta, social_proof, urgency, trust, form_friction, mobile, speed); ranked findings (severity × lift × effort), every finding element-anchored + benchmark-cited.
- 7 layers: SKILL.md router (268L) · 8 references · 13 learnings · 60 registry teardowns · 8 recipes (one per surface) · AGENTS.md + DEPLOYMENT.md · 4 enforcement scripts.
- Composes downstream: routes fixes to SpiderPublish / copy-engine / section-designer; hands the plan to cro-actions (opvs-protocol handoffs, not hard peers).
- Peers: @opvs-ai coordination skills (agentdocs/agentboard/agentmemory/opvs-protocol), all ≥beta — cro-audit is the unblocked root of cluster B.
Showing all 5